Keep sensitive work local
Run inference and retrieval against internal documents on your own network. Configure prompts, source files, embeddings and outputs to stay within your environment.
Sovereign AI · FlexPondi + VS Platform
Put AI to work where your data lives. FlexPondi brings two ASUS Ascent GX10 AI supercomputers into a compact mini rack. VS Platform helps you deploy, secure and manage the local solution from one portal.
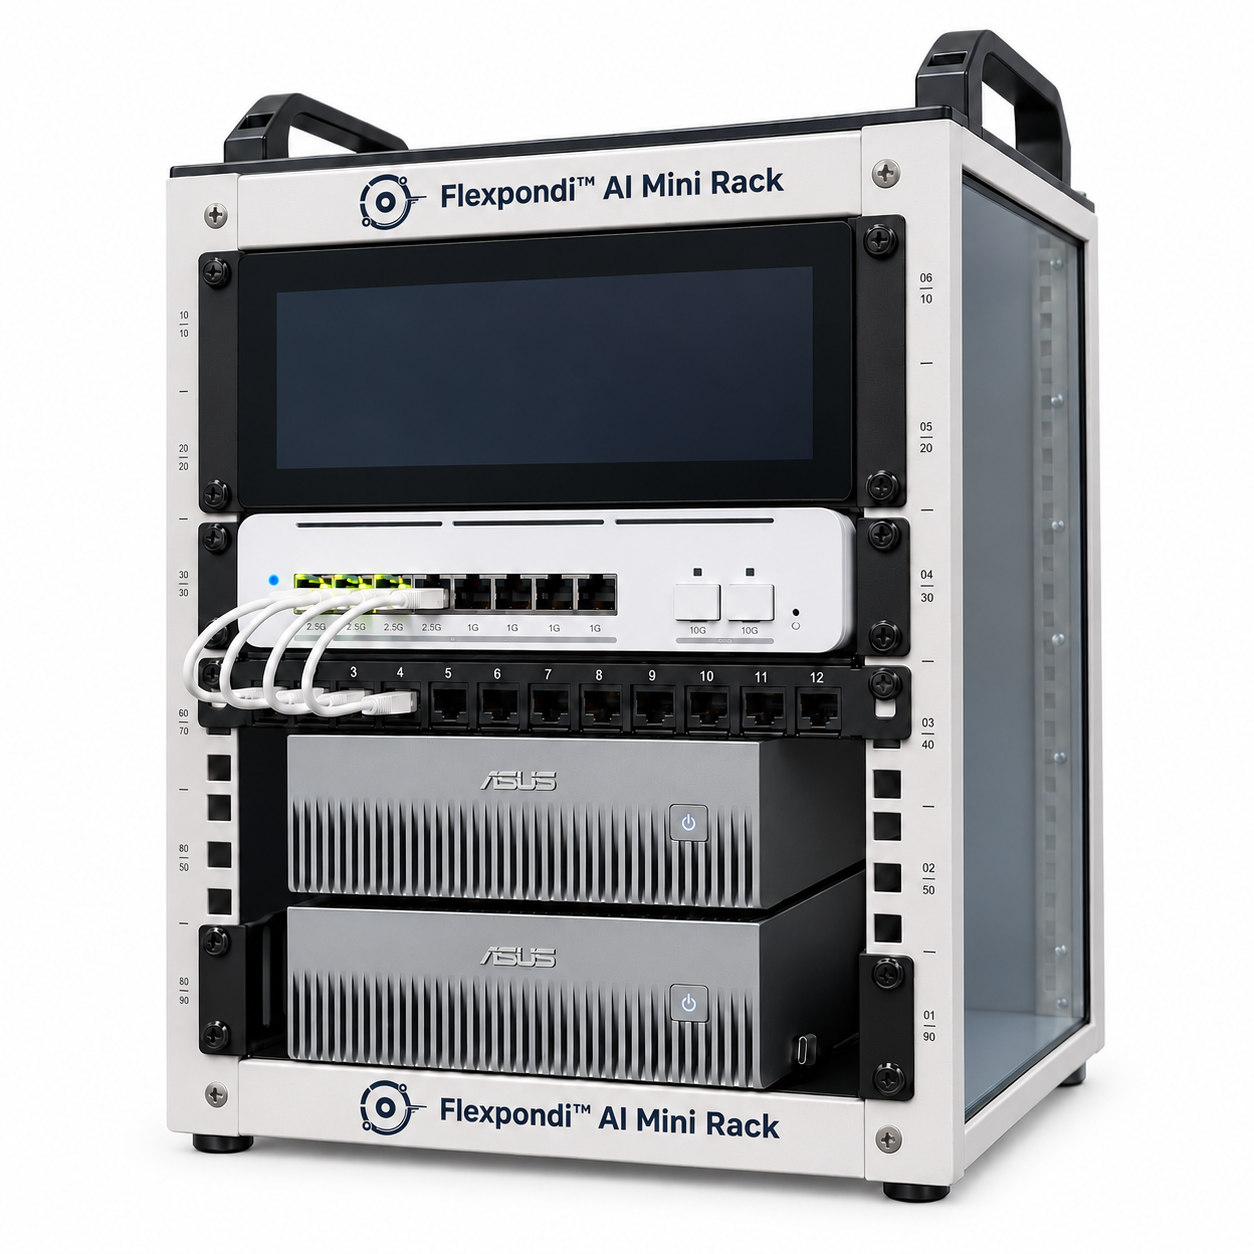
Product visualization based on supplied photography. Two 128 GB models; memory remains distributed across nodes.
Why sovereign AI
Sovereign AI puts your organization in charge of where its AI runs, how data is used and who can access it. Local compute makes that control practical when paired with clear policies and managed operations.
Run inference and retrieval against internal documents on your own network. Configure prompts, source files, embeddings and outputs to stay within your environment.
Select models and tools that fit your workflows, licenses and capacity. A private Ollama deployment gives teams a local starting point for assistants and LLM applications.
Set access and deployment policies, control updates and monitor the infrastructure. Bring the same repeatable approach to the next department or location.
Use owned compute for recurring workloads and reduce reliance on metered inference APIs. Size the system for your models, concurrent users and response-time needs.
The complete local solution
FlexPondi™ AI combines compute, networking, rack infrastructure, software and deployment support in one bundle.
Two ASUS Ascent GX10 systems use the NVIDIA GB10 Grace Blackwell platform also found in DGX Spark. Each selected node has 128 GB of unified CPU/GPU memory. A dedicated high-speed interconnect supports compatible distributed workloads, while the 10G switch connects the solution to your local network.
Explore FlexPondi AI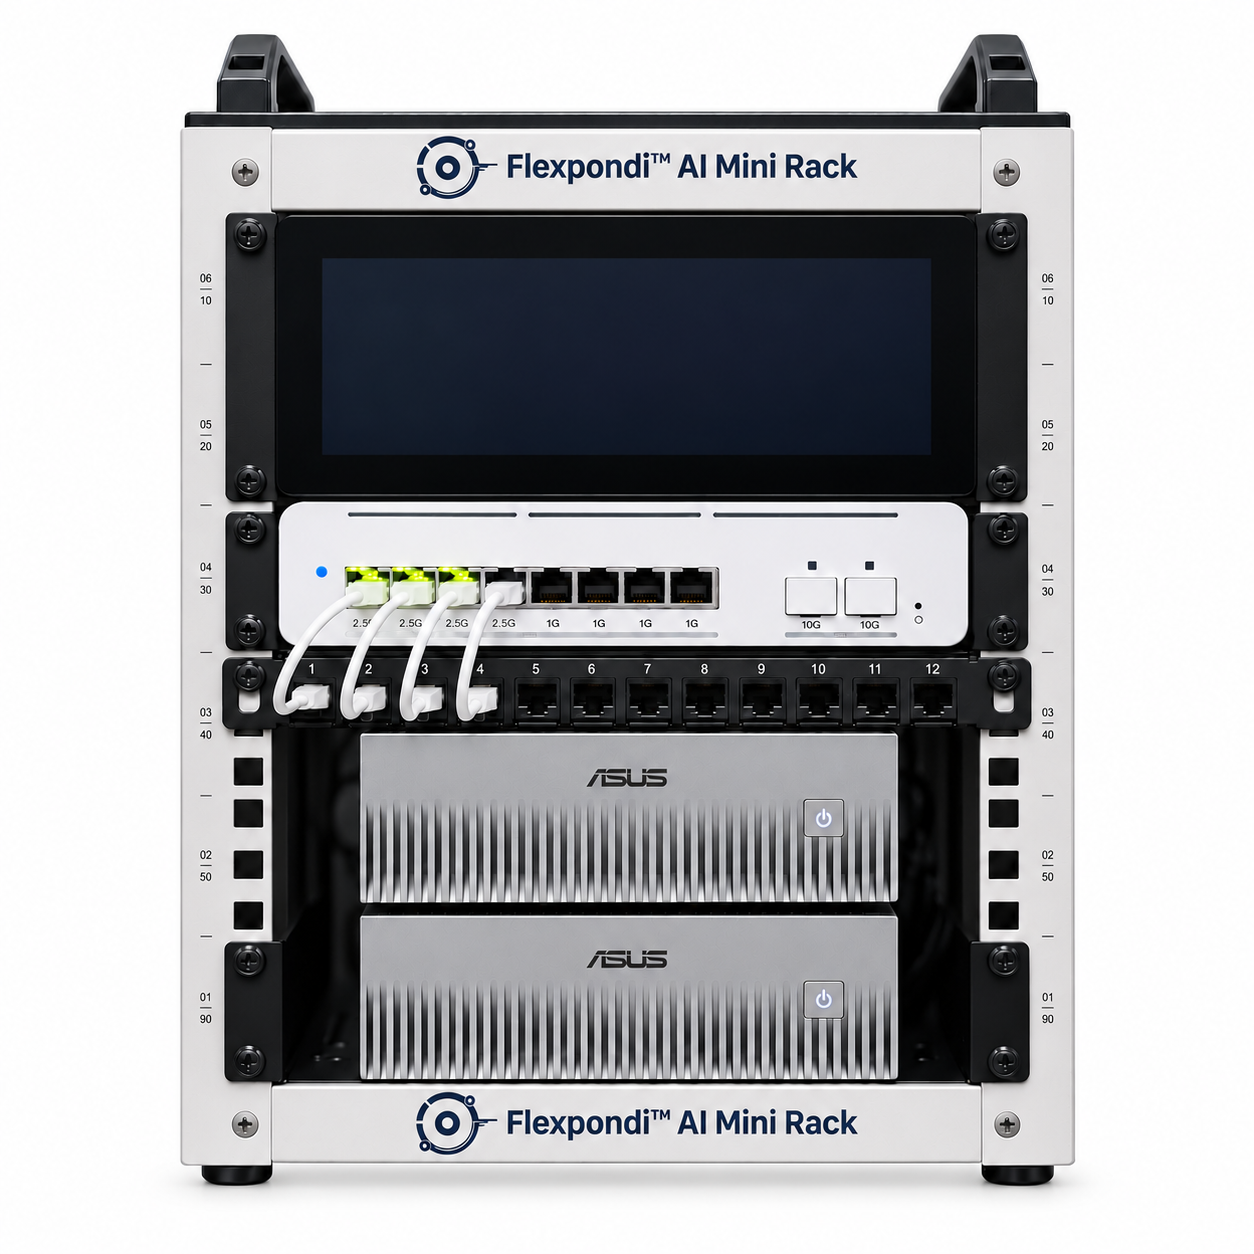
256 GB is the total across two 128 GB systems, not a single shared memory space. Larger-model inference requires a supported distributed runtime, suitable quantization and sufficient memory for context and runtime overhead. Validate the target model and user load before deployment.
One platform for every edge location
VS Platform connects the hardware to an operating workflow: deploy approved services, enforce security policy and keep the solution supported throughout its life.
Onboard supported nodes and roll out applications and AI services through a solution catalog. Establish a consistent configuration for each location.
Solution catalogUse VS Platform’s hardware-backed identity and attestation on supported hardware, encrypted connectivity, role-based access and central policies.
Platform securityMonitor health and security posture, coordinate updates and manage the application lifecycle through one portal as your footprint grows.
Meet VS PlatformDefine your data boundary
A private deployment starts with a clear map of what stays on-site and what is allowed to connect.
Configure applications to keep inference and retrieval local. Review outbound APIs, telemetry, backups, remote access and agent tools against your data policy. Central management and local inference serve different purposes.
Local hardware alone does not establish regulatory compliance or an air-gapped environment. VS Platform’s remote operations require connectivity; verify supported hardware and the management data flow during solution design.
Put it to work
Search and summarize approved internal material through local retrieval and inference, with access aligned to the underlying information.
Enterprise teams · Private AI labsHelp teams query manuals, maintenance procedures and site knowledge close to the systems and people doing the work.
Manufacturing · Warehousing · RetailPrototype agents and AI applications on a Linux and NVIDIA CUDA foundation, then validate the workload before broader rollout.
Robotics · Security operations · Edge computingIt means designing for organizational control. Inference can run locally, but configured applications, external tools, monitoring, backups and remote management may move data. Define and validate those flows as part of deployment.
The ASUS Ascent GX10 is ASUS’s own system based on the NVIDIA GB10 Grace Blackwell platform used in NVIDIA DGX Spark. This bundle specifies two ASUS Ascent GX10 systems with 128 GB of unified memory each.
No. A parameter count alone does not determine fit or speed. Precision, quantization, context length, runtime support and concurrency all affect capacity. Validate the exact model and distributed runtime on the two-node configuration.
No. Nodes can serve separate workloads or participate in supported distributed inference. Resilience and failover require an application architecture and configuration designed for that purpose.
The bundle includes a private Ollama local LLM deployment, deployment support and 12 months of VS Platform subscription service from the time of purchase. Confirm ongoing subscription and support options with Portal Robotics.
Enterprise AI. Anywhere.
Walk through your workload, data boundary and two-node deployment with Portal Robotics.
A 30-minute walkthrough of VS Platform on your use case: onboarding a node, standing up a secure network, deploying from the catalog, and seeing it all in one portal.